OpenAI says its newest models have gone from almost useless to near-perfect at one of enterprise software’s oldest jobs: translating COBOL. In a research post published on October 19, “Advancing coding in low-resource programming languages,” the company reported that GPT-6.1 Sol correctly migrated 97.9% of COBOL programs in its own migration test at higher reasoning effort, up from 5.4% for the previous generation’s GPT-5.6 Sol — and released one of its two new evaluations publicly so other developers can check the other half of the claim.
The work targets what OpenAI calls low-resource programming languages — COBOL, Fortran, Visual Basic, OCaml and others with far less public code and documentation for models to learn from than Python or JavaScript. OpenAI says developers and enterprise customers kept telling it that coding models struggle with exactly these languages. All three models discussed in the post — GPT-6 Astra, GPT-6.1 Sol and GPT-6 Luna — are available through OpenAI’s API.
https://x.com/OpenAI/status/2112310345863930168
The COBOL Migration Evaluation: 5.4% To 97.9%
OpenAI built a COBOL migration evaluation that asks a model to convert existing COBOL programs into C++, Java, Kotlin, Python or Rust. Hidden tests demand identical observable behaviour — a migration counts only if every test passes, byte-for-byte on output. At low reasoning effort, GPT-6.1 Sol scored 86.6%, against 5.4% for GPT-5.6 Sol at the same setting, while costing 39% less in API terms. At higher reasoning effort it reached 97.9%, which OpenAI describes as close to saturating the test.
The company is careful about the limits, and the article should be too: both evaluations are OpenAI’s own, the COBOL migration test itself has not been published, and the figures have not been independently checked. OpenAI also stresses that migrations of production software still require expert review and testing against a system’s actual business rules before anyone ships them.
MultiLangBench: Building SQLite In 20 Languages
The second evaluation, MultiLangBench, asks a model to build a SQLite-compatible database engine from scratch in one of 20 programming languages over a long coding session, checked against tests adapted from SQLite’s own suite. OpenAI has released the MultiLangBench setup and test suite on GitHub, which makes this half of the announcement verifiable by anyone.
At maximum reasoning effort, the flagship GPT-6 Astra averaged an 87.4% test pass rate, up from 26.8% for GPT-5.6 Sol, and improved in every language, scoring above 83% in 19 of the 20. The biggest gains were in the oldest languages: COBOL rose from 10.9% to 72.1% — still the hardest language in the set — Fortran from 21.4% to 83.5%, Visual Basic from 27.5% to 89.4% and OCaml from 25.6% to 85.8%. The budget model, GPT-6 Luna, averaged 40.3% at an estimated $0.77 per sample against $3.48 for GPT-5.6 Sol — about 78% cheaper — though its COBOL score rose only from 10.9% to 17.1%.
Why Legacy Languages Carry So Much Weight
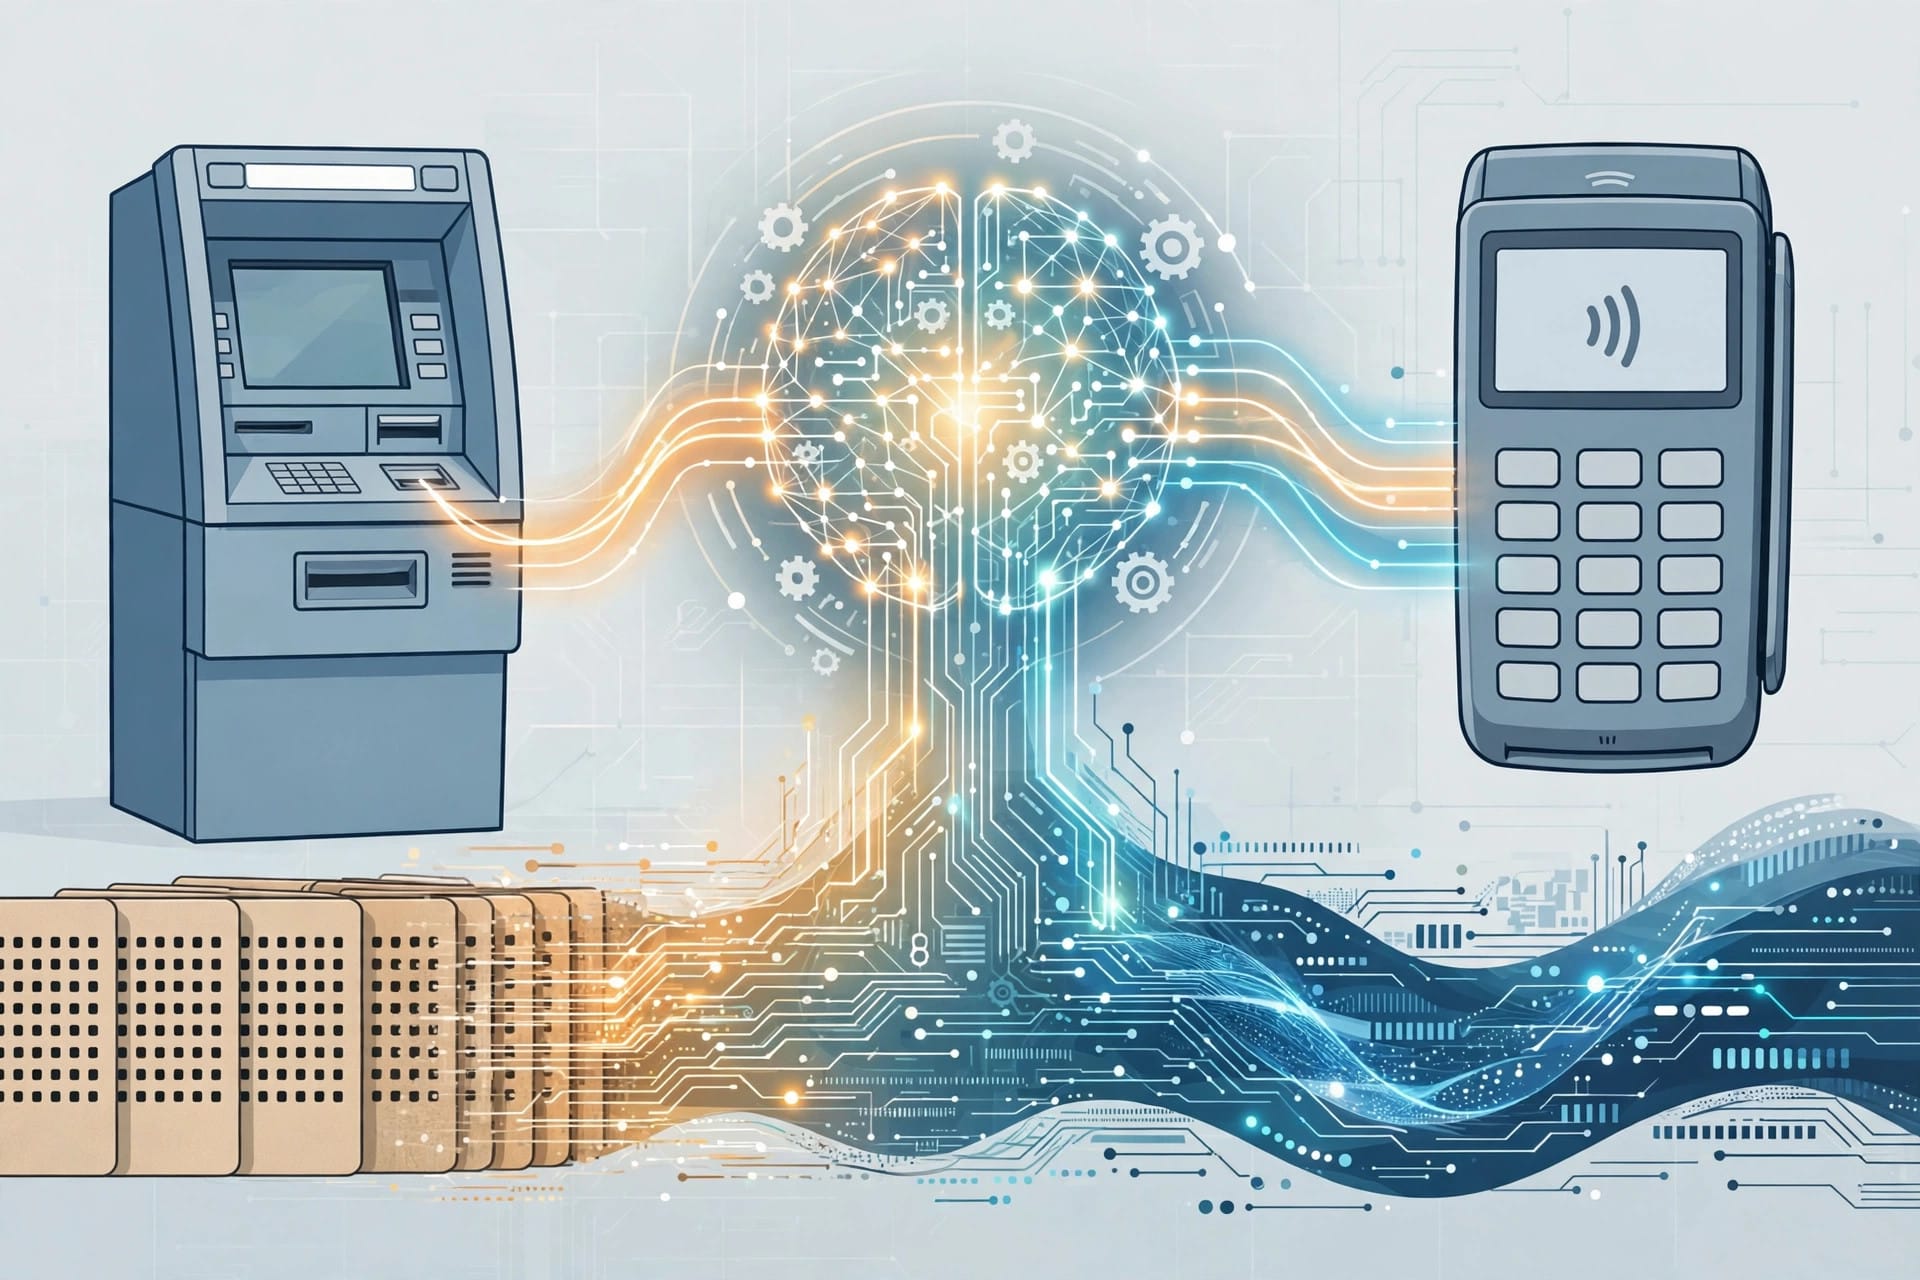
These languages are old, but they are not niche. OpenAI cites IBM figures that COBOL supports more than 40% of online banking systems, 80% of in-person card transactions and 95% of ATM transactions, while Fortran still runs weather forecasting and nuclear reactor safety analysis. The people who wrote much of that code have retired, documentation is patchy, and key business rules may exist only inside the code itself.
That makes rewriting risky in ways a pass rate cannot capture. OpenAI’s own example: COBOL’s fixed-point arithmetic discards extra decimal digits unless rounding is explicitly requested, so a modern rewrite that rounds instead can run without a single error while quietly producing different financial results. It is the same preservation problem GERoundtable’s explainers flag across AI coding tools generally — generating replacement code is easy; proving it behaves identically is the work.
Why It Matters
The central entity here is GPT-6.1 Sol’s COBOL migration capability, and its neighbours are the banks, insurers and governments that have spent decades trying — and often failing — to move off mainframe code because rewrites are slow, costly and easy to get subtly wrong. If OpenAI’s numbers hold up outside its own tests, legacy modernisation becomes a serious enterprise market for the lab, which is why the story belongs with OpenAI’s wider platform push: the same models are already being picked as defaults by developer platforms, as when Replit made OpenAI its default for Replit Agent, and they sit inside the line-up GERoundtable compares in its guide to ChatGPT’s models. The honest caveat travels with the headline: the migration benchmark is unpublished and self-run, and OpenAI does not compare its models with rivals such as Claude on these tasks.
Background
COBOL was designed in 1959 and became the backbone of banking, government and insurance systems; an estimated hundreds of billions of lines remain in production because replacing them has repeatedly proven riskier than keeping them. AI coding assistants historically performed worst exactly there, for lack of training data. OpenAI’s October 19 post is its first dedicated attempt to close that gap with purpose-built evaluations — one released openly on GitHub, one kept internal — aimed squarely at the enterprise modernisation market.
Source: MadRobot and Thurrott, reporting OpenAI’s official October 19 research post “Advancing coding in low-resource programming languages” and its MultiLangBench release on GitHub

0 Comments